The Agent Sandbox is the workspace where you create and edit AI agents, for every organization. You describe what you want in a chat or set the agent up by hand, test it on your own products, see exactly what it generates, and refine it until it is right, all in one place. It is the fast, low-stakes way to get an agent performing the way you want before it touches a real enrichment job.

How it works

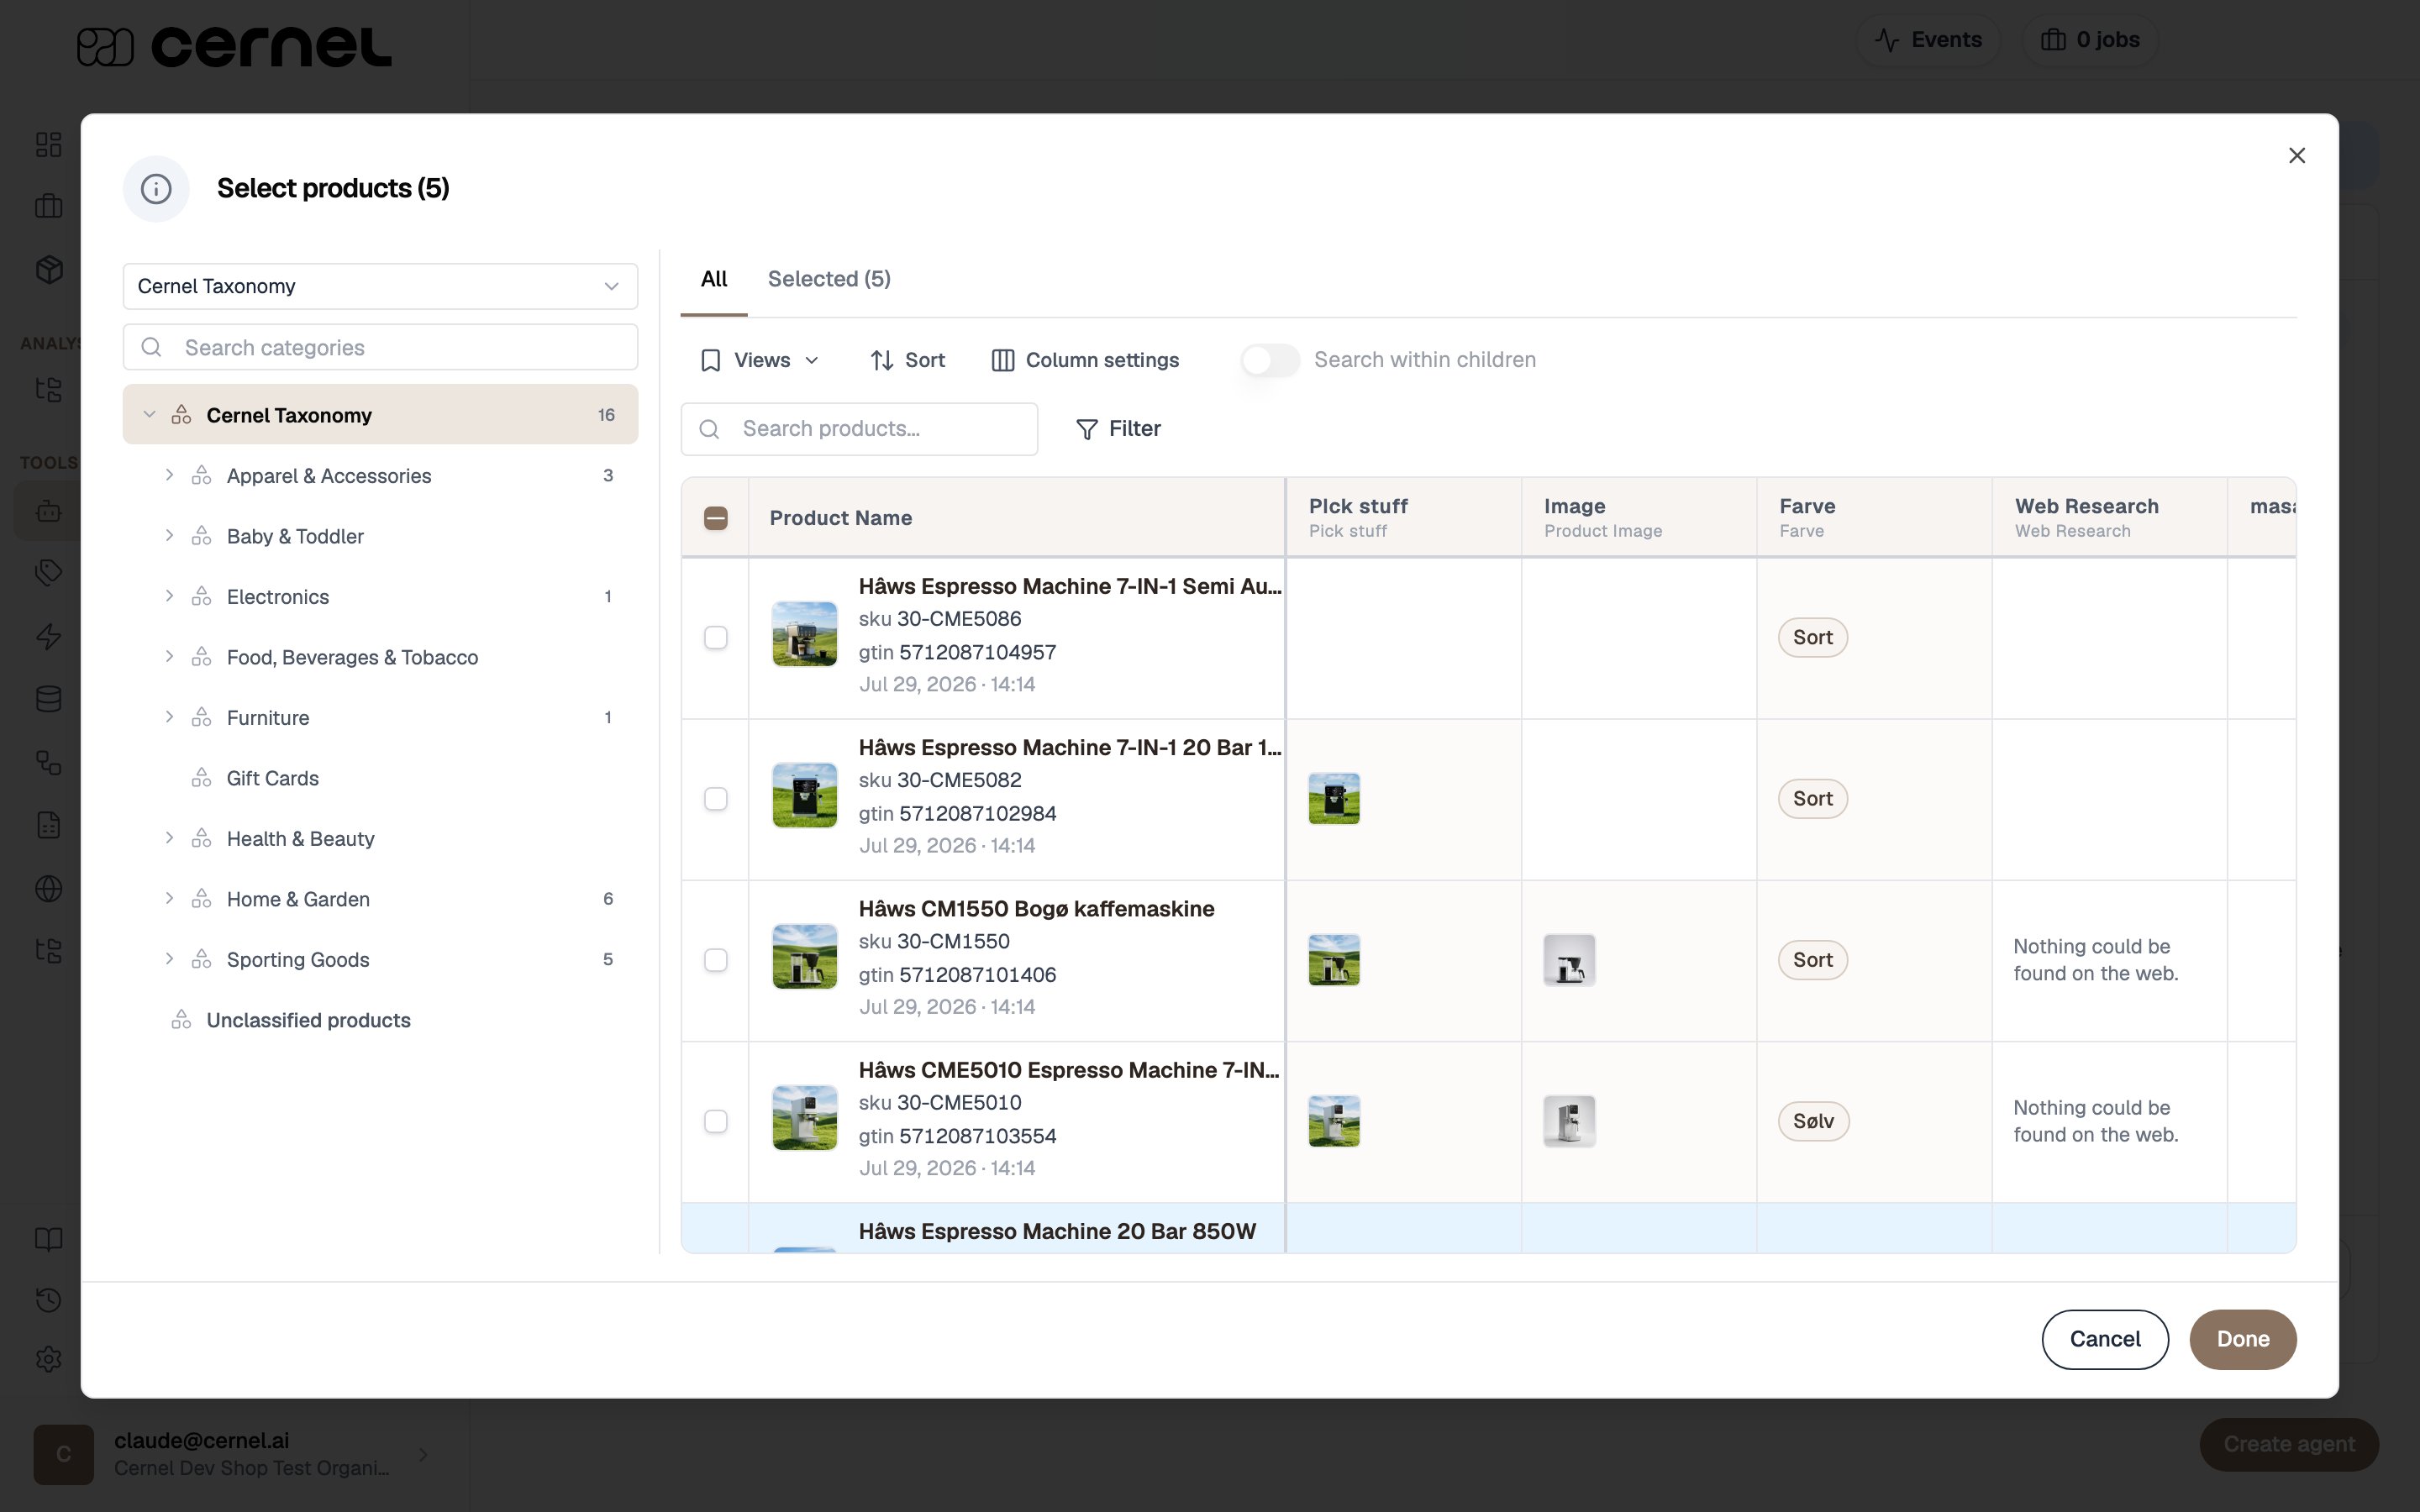
The sandbox is a full page. On the right is a chat that helps you build and adjust the agent. On the left is everything about the agent, laid out as tabs:
  • Test: pick a handful of real products and run the agent on them to see live results.
  • Prompt: the agent’s prompt instructions.
  • Review Steps: the quality checks that hold back weak enrichments. Review Steps is an add-on module that is not enabled by default. See Review Steps.
  • Options: for classification agents, the values the agent can choose from.
  • Languages, Dependencies, and Advanced Settings: the rest of the agent’s configuration.
  • Changes: the agent’s history. Unsaved changes lists the changes made in this session, and Saved versions lists every version of the agent that has been saved, newest first.
You do not have to hand-write a long prompt. You tell the chat what you want, in plain language, and it drafts or rewrites the agent’s prompt for you, saving each rewrite as a new version you can step back to. When the output on your test products looks right, you create or save the agent, and it is ready to be linked to attributes and run at scale.

Why you would use this

Catch problems before they hit your catalog

See the agent’s output on real products first. Fix tone, structure, and accuracy on a handful of samples instead of discovering issues across thousands of enriched products.

Build the agent in chat, not in a prompt editor

Describe what you want in plain language. The chat drafts and rewrites the prompt for you, faster than hand-editing a long prompt and guessing at phrasing.

Step back through versions

Every rewrite is saved as a version in the Changes tab, so you can compare wordings and return to any earlier one that worked better.

Use real products, not synthetic tests
The sandbox runs against your own product data, so what you see is what enrichment will actually produce.
Key concept: the agent chat. The chat does not just comment on the output. It builds and rewrites the agent’s prompt based on what you ask, and saves each change as a new version. After a rewrite, click Run test on the Test tab to generate fresh output, or ask the chat to run the test: it runs the agent on your selected products and explains the results.
The Agent Sandbox page showing the agent chat alongside the configuration tabs and a live test-run results view

The Agent Sandbox: the chat that builds the agent alongside the configuration tabs and live test results

Step-by-step guide

1

Open the sandbox

Create a new agent, or edit an existing one, to open it in the sandbox. Editing an existing agent brings its current configuration into the workspace so you can refine it the same way you built it.
2

Start the agent

A new agent opens on a start screen that asks What should your agent do? You can begin in four ways:
  • Describe your intent and let the chatbot draft the agent for you. Optionally pin the agent type first.
  • Use a template to start from a ready-made agent in the template library. Search it, filter by type, and click Use template; the sandbox opens with the template’s configuration staged so you can test it right away.
  • Copy from existing to start a new agent from the settings of one you already have.
  • Manual input to enter the name, type, and prompt yourself.
When you arrive from a category’s Add New Attribute dialog, the start screen also offers Use existing agent, which links an agent you already have to the attribute without creating a new one.Whichever way you begin, you land in the same workspace and can adjust everything from there.
If you let the chatbot draft the agent, it takes a moment to prepare it. You will see The chatbot is still drafting the agent. You can create it once the draft is ready, and the Create agent button becomes available as soon as the draft is done.
3

Review the configuration tabs

Use the tabs to check and adjust the agent: the Prompt, any Review Steps that should guard its output (an add-on module, not enabled by default), the classification Options if it is a Single or Multi Select agent, and the Languages, Dependencies, and Advanced Settings. You can keep refining the prompt through the chat at any point.
4

Pick products and run a test

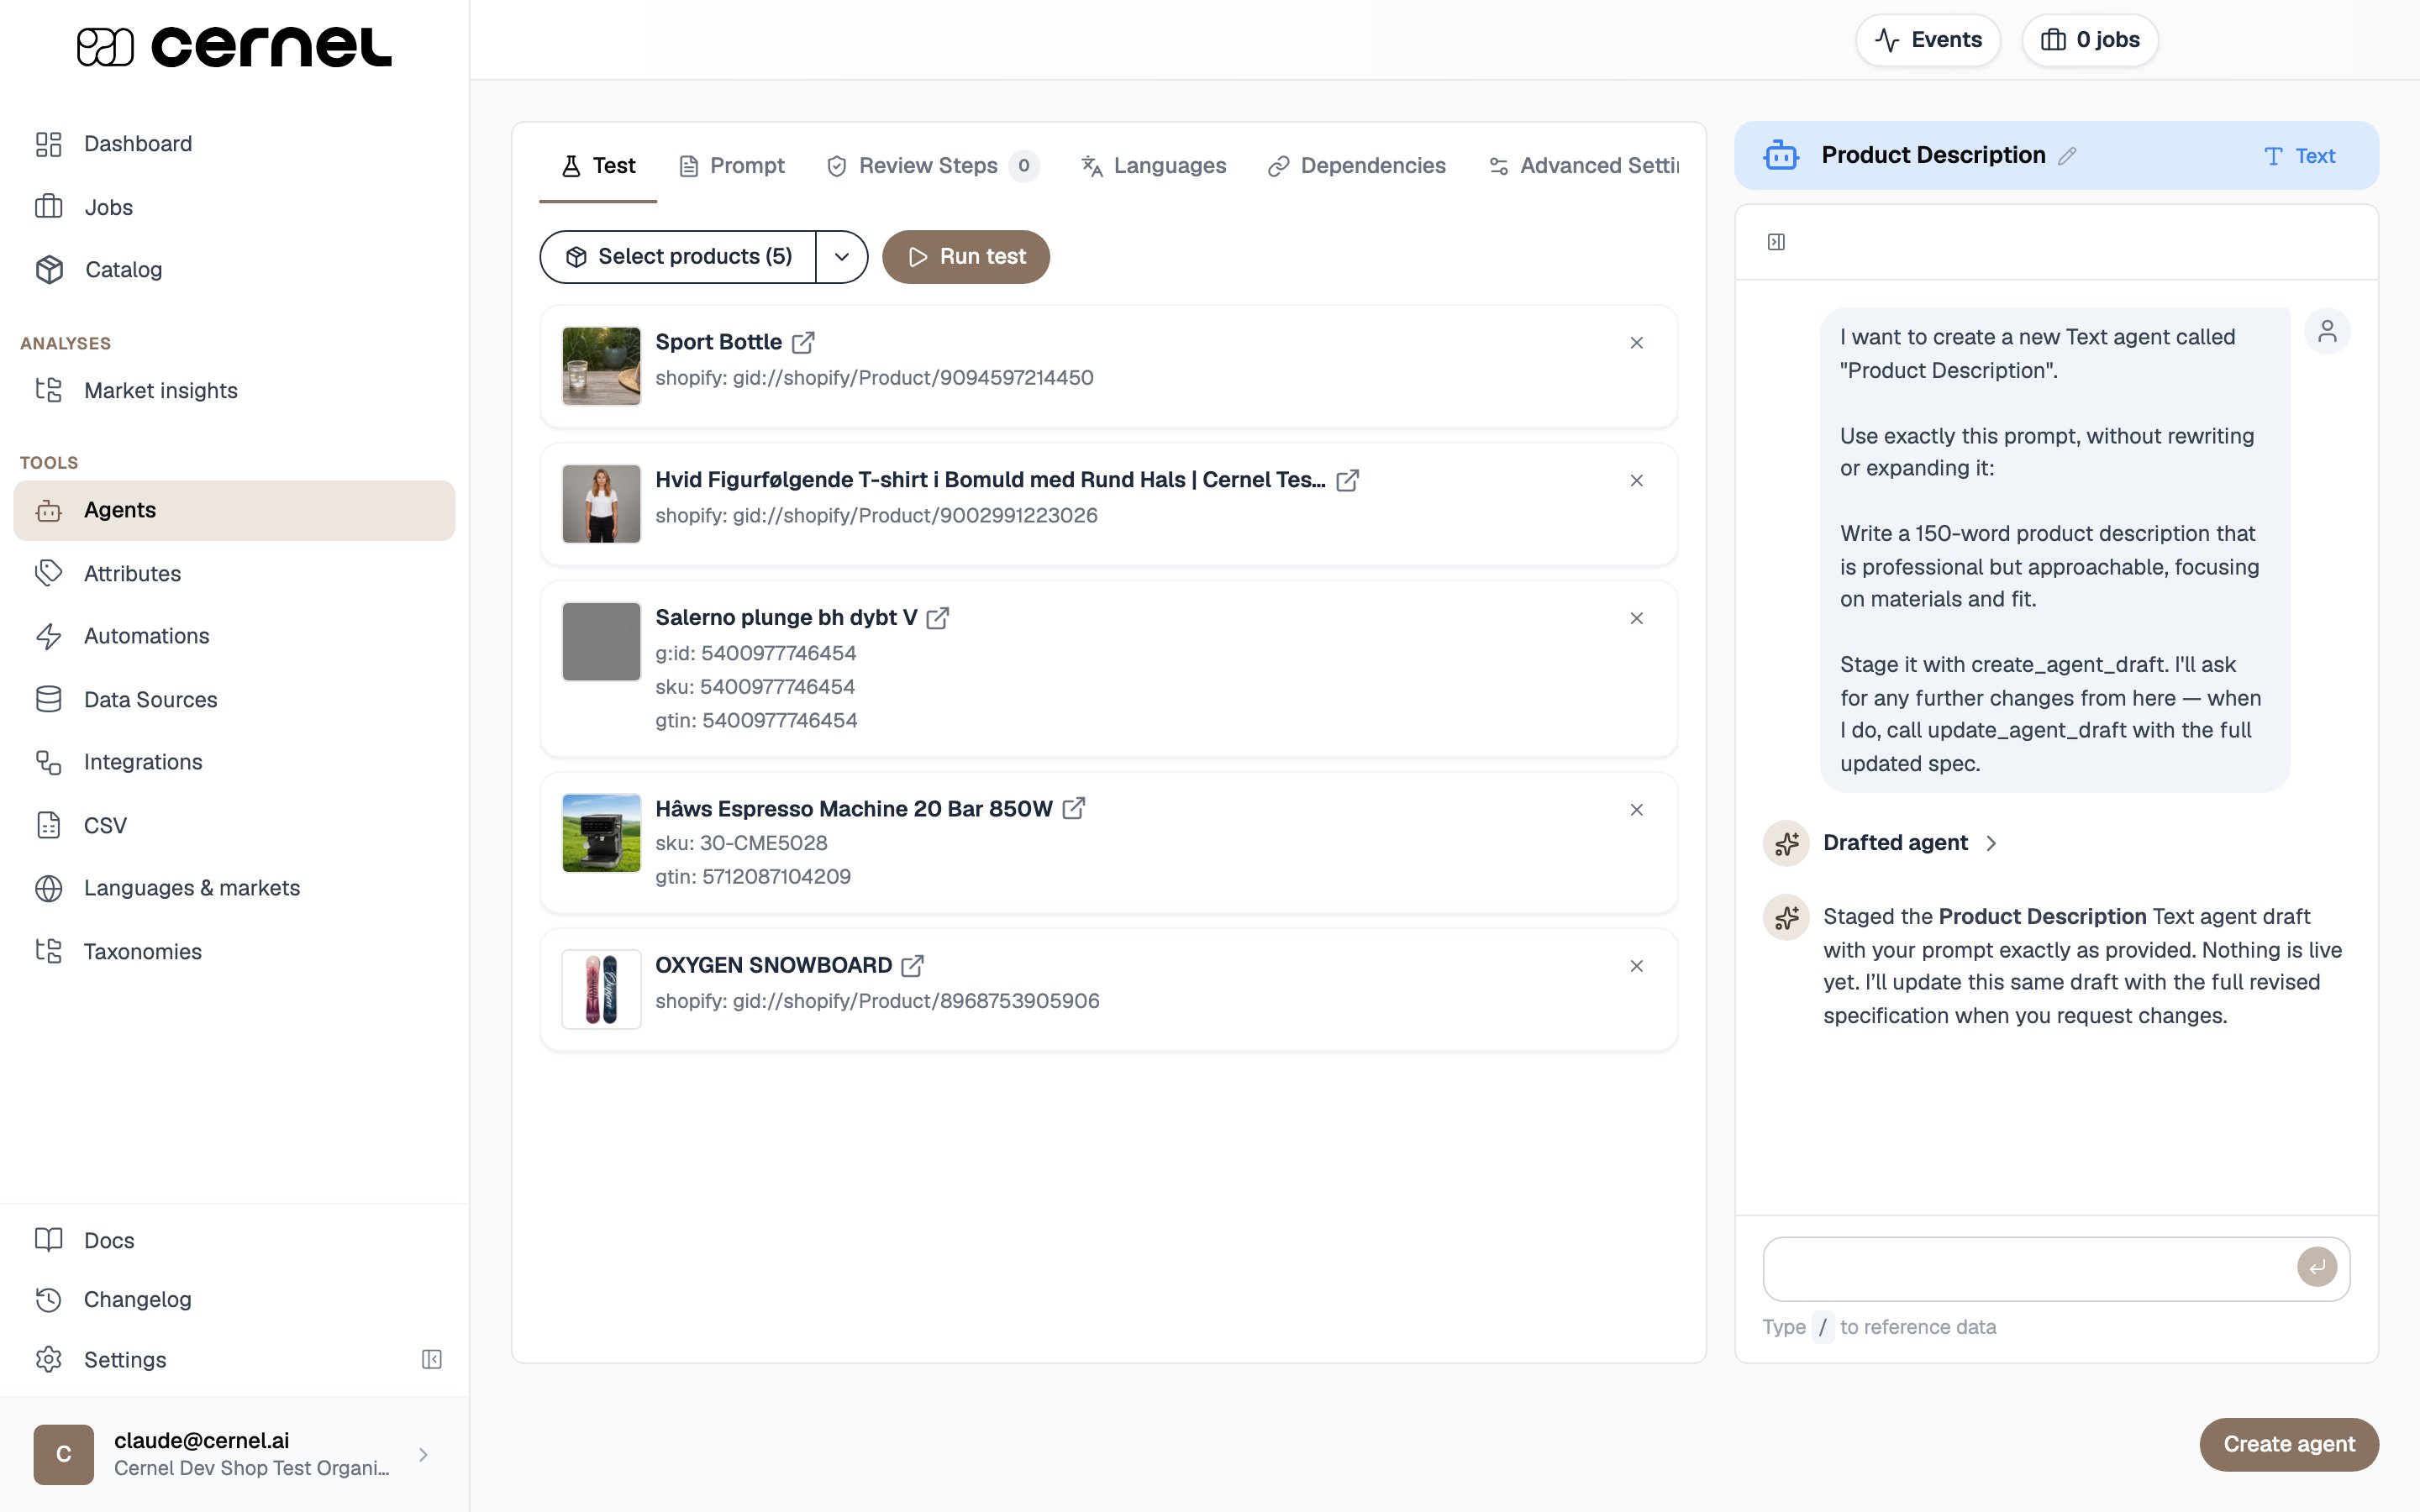
On the Test tab, the sandbox has already picked five products for the agent to run against. To change them, click Select products (5) to search and pick up to 10 by name, or open the arrow beside it and choose Select 5 random products for a fresh sample, from the category you’re working in or from your entire catalog. When the agent depends on other attributes, the random pick prefers products that already have those values. Then click Run test.Results stream in live, one product at a time. Each card shows the product and the value the agent generated, updating as soon as that product finishes so early results appear while the rest are still running. While a run is in progress the button becomes Stop, which stops the run immediately and keeps any results that already came back.
The Select products dialog for a test run, with the category tree on the left, a searchable product table to pick from, and a Selected tab showing the current picks
Pick a mix that represents what enrichment will actually face: different product types, price points, and levels of input data. Catching edge cases here saves you from discovering issues across thousands of enriched products later.
5

Review the results

For any result you can:
  • Read the AI Reasoning to see how the agent arrived at the value.
  • Click View details to open a drawer with the compiled Prompt the model received, the Source Data it used as context, and the Result in full.
  • Open View live agent thinking on a card to watch the agent reason as it works, useful for longer-running External Data and Media agents.
  • Open Checks to see how the agent’s review steps judged the value, if it has any.
If a product failed, its card shows an error state, and you can still open its thinking to see what the agent did before the error.
6

Refine through chat

If the output needs work, tell the chat what to change, for example “Make the descriptions shorter, aim for 80 to 100 words” or “Don’t mention competitor brands.” The chat rewrites the prompt and saves it as a new version. Click Run test to see the rewritten prompt in action, or ask the chat to test it for you.
Type @ in the chat to reference a specific product from your current results. The chat picks up that product’s generated output and reasoning, so feedback tied to exactly what you are pointing at lands more precisely than a general instruction.
7

Step through versions in the Changes tab

Every rewrite creates a new version. Open the Changes tab to see the history. Unsaved changes lists this session’s changes, newest first; they become a saved version when you click Save agent. Saved versions lists every version of the agent that has been saved, newest first, with who saved it and their comment. On a new agent the tab lists this session’s changes, starting from Initial version. Select any version to see what it changed compared with the version before it, and use Restore this version to return to the wording you liked.
8

Create or save the agent

When the output is where you want it, click Create agent for a new agent, or Save agent for an existing one, where you can add an optional comment describing what changed. The current prompt is committed and linked to the agent, which is now ready to be linked to attributes and run through enrichment.
The agent is saved with the prompt you tested. Running enrichment with it will produce output similar to what you just saw in the sandbox.
The sandbox doesn’t run an agent’s dependencies before testing. If your agent depends on other attribute values (for example, a Meta Description agent that reads Product Description), pick products that already have those upstream values filled in. Otherwise the sandbox will show weaker output than enrichment would produce once dependencies are in place.

Advanced configuration

The agent chat supports @ mentions. Typing @ opens a list of the products in your current test run. Click one to insert it as a pill into your message. When the chat rewrites the prompt, it uses that product’s generated output, reasoning, and images as grounded feedback, not just the text you typed.Use this when one product is off but the rest look fine. Instead of rewording the entire prompt, point the chat at the outlier and describe what is wrong with it specifically.
The detail drawer (View details on any result) shows three things:
  • Prompt: the compiled prompt sent to the model for that product, with Data Source references and product fields already filled in. If the output is surprising, check the compiled prompt first to see whether the right context made it in.
  • Source Data: the product attributes the agent used as context, including the product name, images, and any referenced fields.
  • Result: the generated value on its own, rendered the way the product table will render it.
Comparing the Prompt and Source Data between a good product and a bad product usually pinpoints an unexpected output quickly.
The Changes tab lists this session’s Unsaved changes and the agent’s Saved versions. Selecting a version shows what it changed compared with the version before it, section by section (name, prompt, review steps, options, languages, and settings), each marked Added, Removed, or Edited. Use Restore this version to make an earlier version current again. Restoring a saved version saves it again as the newest version, and reloads the agent, so any unsaved changes and the chat are discarded. If a direction is not working, return to a version you liked and start refining from there.
If you change the agent’s output type while building it (for example, from Text to HTML, or from Single Select to Multi Select), the chat adapts the prompt for the new type so the instructions match what the new type expects. Re-run the test to see output in the new format.
  • Saved with the agent: the prompt as it stands when you create or save, plus the configuration you set on the tabs. Each save adds a version under Saved versions in the Changes tab.
  • Not saved: the list of test products, individual test results, and the agent chat transcript.
When you reopen the agent later, the sandbox starts fresh. The agent carries forward the prompt you saved, but the conversation that produced it is not stored.

Frequently asked questions

Two common causes:
  1. The agent has dependencies that haven’t been filled in on the test products. The sandbox doesn’t run upstream agents first. If your agent reads other attribute values, pick test products that already have those values.
  2. The selected products don’t represent your catalog well. Choose Select 5 random products again, or hand-pick a mix of product types and price points. Outputs can vary a lot between, say, a simple t-shirt and a technical running shoe.
Open the Changes tab, find the version you want under Unsaved changes or Saved versions, and use Restore this version. Unsaved changes are this session’s rewrites; saved versions are every version of the agent that has been saved, newest first. Restoring a saved version discards any unsaved changes and the chat.
The chat calls the model once to draft or rewrite your prompt for the new instruction. That is a small, fast call. A test run happens when you click Run test or ask the chat to run one, so you decide when the slower enrichment pass happens. Keep chat messages focused: one clear change per message is easier to verify than a long instruction that rewrites several things at once.
Yes. While a run is in progress, the Run test button becomes Stop. Click it to stop immediately: Cernel keeps any results that already came back, marks the rest Stopped before this product got a result, and brings back Run test so you can adjust and try again. This is especially useful for External Data agents, whose research passes can take a couple of minutes.
Yes. If the agent has review steps, each test result includes a Checks view showing how they judged the value. This lets you tune the review-step prompts against real output before the agent runs at scale. See Review Steps.
The agent chat transcript isn’t stored. The prompt you saved with the agent is kept, but the conversation that produced it is discarded. If you reopen the agent, the sandbox starts fresh.

What’s next

Review Steps

Add quality checks that hold back or reject weak enrichments before they reach your catalog.

AI Agents

Learn the full agent setup: prompts, Data Sources, dependencies, and linking agents to categories.

Your First Enrichment

Take a sandbox-tested agent and run it across a full category.

Data Sources

Plug brand guidelines and context libraries into prompts so sandbox output lines up with your brand.